ZenDNN 6.0: FP16 Inference and MoE Acceleration on AMD EPYC™ CPUs
ZenDNN 6.0 takes the next step: FP16 functional support for AMD’s 6th Gen EPYC™ processors, MoE model optimization, and the vLLM compatibility window.
ZenDNN is a deep neural network acceleration inference library optimized for AMD “Zen” CPU architecture. ZenDNN library comprises of a set of fundamental building blocks and APIs designed to enhance performance for AI inference applications primarily targeting AMD EPYC™ server CPUs. ZenDNN plugs into mainstream AI frameworks offering developers seamless experience in developing cutting edge AI applications. This library continues to redefine deep learning performance on AMD EPYC™ CPUs, combining relentless optimization, innovative features, and leading-edge support for modern workloads.
Delivers high performance over diverse AI workloads such as LLMs, NLP, Vision, and Recommendation Systems without significant engineering efforts offering ease of integration into existing x86 DL environment.
Provides freedom of vendor choice by building upon open-source projects such as oneDNN. ZenDNN offers zero to minimal code modifications for existing x86 applications and at the same time supports additional APIs designed to deliver higher performance.
ZenDNN is optimized to benefit from higher core counts and large L3 caches on AMD EPYC CPUs helping users derive TCO advantages.
ZenDNN Provides:
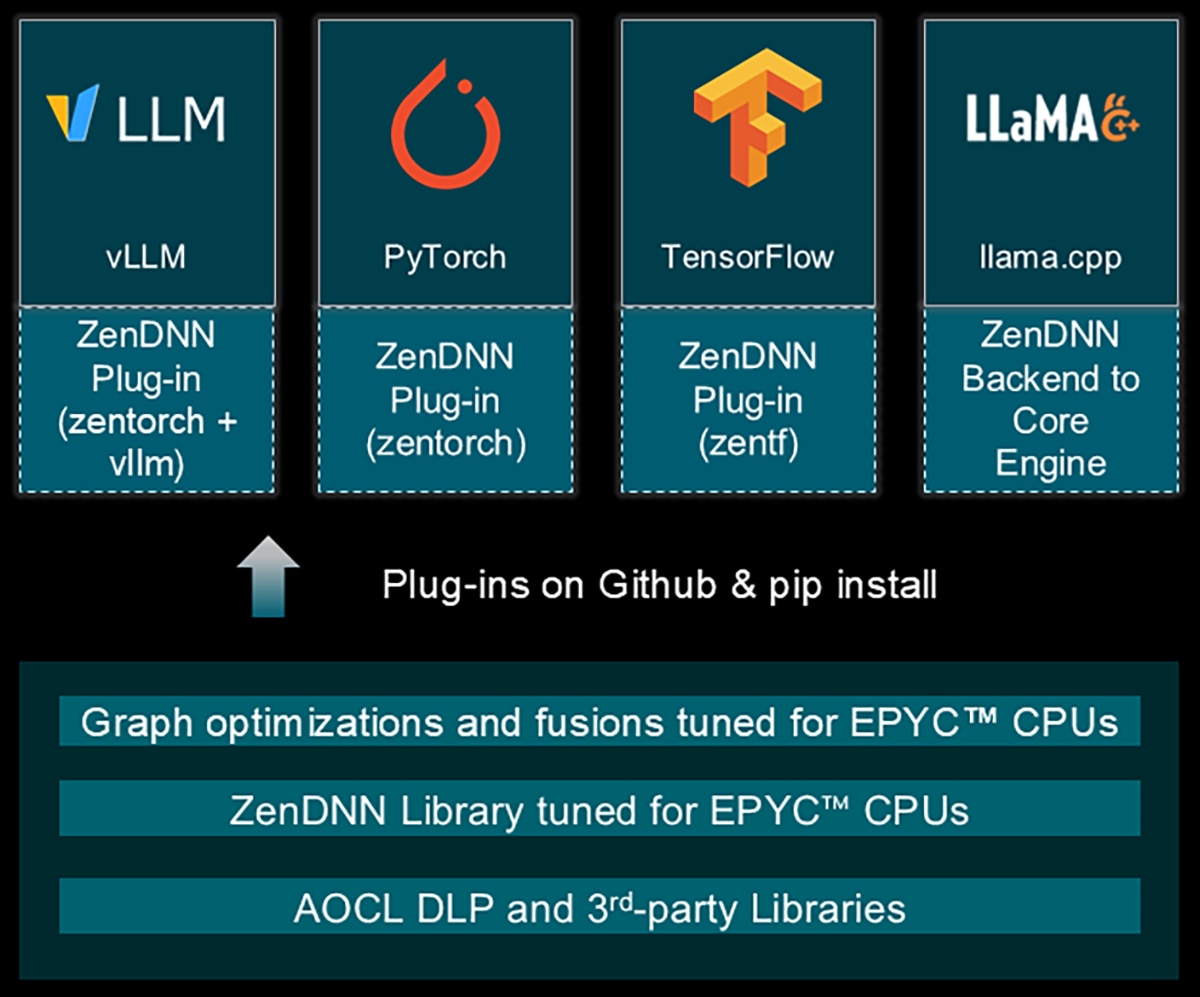
Below is a comprehensive ZenDNN User Guide that covers the release highlights and installation instructions for PyTorch and TensorFlow. For the performance tuning enthusiasts, learn about extra tips and tricks under the Performance Tuning chapter. To read more about current and previous releases, check out the ZenDNN Release Blog tab.
ZenDNN Library: https://github.com/amd/ZenDNN
ZenDNN Plugin for PyTorch: https://github.com/amd/ZenDNN-pytorch-plugin
ZenDNN Plugin for TensorFlow: https://github.com/amd/ZenDNN-tensorflow-plugin
Get started with ZenDNN to enhance AI performance on AMD EPYC™ server CPUs.
To read more about current and previous releases, see the AMD Technical Articles and Blogs.
ZenDNN 6.1.0 builds on the 6.0.0 LowOHA inference stack. It makes group-matmul custom kernels faster and adds FP16 and DA8W4 kernels, adds matmul custom kernels for DA8W4, DA8W8, INT8, and BF16, and adds GQA and sliding-window flash attention, a routed-MoE API, and in-place weight caching by default.
zentorch for ZenDNN 6.1 elevates FP16 from functional to performance-qualified on Venice, adds DA8W4 quantization for both dense and MoE models, introduces speculative decoding support, and extends vLLM compatibility through v0.31.0 with eight ZenDNN-authored upstream contributions. New use case classes including RAG embedding models and audio models.
zentf 2.21.0.1 is a plugin-patch release on top of zentf 2.21.0.0. It keeps TensorFlow 2.21.0 as the primary framework version and moves the ZenDNN dependency from v6.0.0 to v6.1.0.
| ZenDNN Plug-in for PyTorch (Built with PyTorch 2.14.1) | Description | MD5SUM |
| ZENTORCH_v2.14.1.0_Python_v3.10.zip | This zip file contains the zentorch wheel file and the necessary scripts to set up the environment variables. Compatible with Python version 3.10 | 75fd5819b21307e9733a9dff74847fc8 |
| ZENTORCH_v2.14.1.0_Python_v3.11.zip | This zip file contains the zentorch wheel file and the necessary scripts to set up the environment variables. Compatible with Python version 3.11 | 11beb417878f98700079d70def8cd575 |
| ZENTORCH_v2.14.1.0_Python_v3.12.zip | This zip file contains the zentorch wheel file and the necessary scripts to set up the environment variables. Compatible with Python version 3.12 | 68c7928168acc01ad201346672083328 |
| ZENTORCH_v2.14.1.0_Python_v3.13.zip | This zip file contains the zentorch wheel file and the necessary scripts to set up the environment variables. Compatible with Python version 3.13 | 06096487cc81bddbda1361faf76757b4 |
| ZENTORCH_v2.14.1.0_Python_v3.14.zip | This zip file contains the zentorch wheel file and the necessary scripts to set up the environment variables. Compatible with Python version 3.14 | 569b9d19f6382cd0357861f58110a0a5 |
| Note: Above packages can be used for non LLM executions | ||
| ZenDNN Plug-in for PyTorch (Built with PyTorch 2.13.0) | Description | MD5SUM |
| ZENTORCH_v2.13.0.3_Python_v3.10.zip | This zip file contains the zentorch wheel file and the necessary scripts to set up the environment variables. Compatible with Python version 3.10 | 774c22ae625f498b72afd40b40cde9e3 |
| ZENTORCH_v2.13.0.3_Python_v3.11.zip | This zip file contains the zentorch wheel file and the necessary scripts to set up the environment variables. Compatible with Python version 3.11 | 35fe130e57dbb067e75b5a3dfdc0883d |
| ZENTORCH_v2.13.0.3_Python_v3.12.zip | This zip file contains the zentorch wheel file and the necessary scripts to set up the environment variables. Compatible with Python version 3.12 | 92d16ba70e4be98001e84ac9d4d96554 |
| ZENTORCH_v2.13.0.3_Python_v3.13.zip | This zip file contains the zentorch wheel file and the necessary scripts to set up the environment variables. Compatible with Python version 3.13 | 3bae565156844f9ba1a9d40f687c0ce1 |
| ZENTORCH_v2.13.0.3_Python_v3.14.zip | This zip file contains the zentorch wheel file and the necessary scripts to set up the environment variables. Compatible with Python version 3.14 | 677b66518bf06059d769e4503b2b00ce |
| Note: Above packages can be used for LLM executions with vLLM and non LLM executions | ||
| ZenDNN Plug-in for TensorFlow (Built with TensorFlow 2.21.0) | Description | MD5SUM |
| ZENTF_v2.21.0.1_Python_v3.10.zip | This zip file contains the zentf wheel file and the necessary scripts to set up the environment variables. Compatible with Python 3.10 | b1436123b51660afa02d306f64ca6dc3 |
| ZENTF_v2.21.0.1_Python_v3.11.zip | This zip file contains the zentf wheel file and the necessary scripts to set up the environment variables. Compatible with Python 3.11 | 5afaab96b85d8fe2be0dcfba366ae913 |
| ZENTF_v2.21.0.1_Python_v3.12.zip | This zip file contains the zentf wheel file and the necessary scripts to set up the environment variables. Compatible with Python 3.12 | f94021a316d2dce2a9286d1b55603689 |
| ZENTF_v2.21.0.1_Python_v3.13.zip | This zip file contains the zentf wheel file and the necessary scripts to set up the environment variables. Compatible with Python 3.13 | 283d962caaa4b72ea6e5b492dd9ea72f |
| ZENTF_v2.21.0.1_C++_API.zip | This zip file contains the ZenDNN TensorFlow Plug-in with C++ APIs | 5e8caa99ecabff31e739734e80934d2d |
| ZenDNN Plug-in for TensorFlow (Built with TensorFlow 2.20.0) | Description | MD5SUM |
| ZENTF_v2.20.0.1_Python_v3.10.zip | This zip file contains the zentf wheel file and the necessary scripts to set up the environment variables. Compatible with Python 3.10 | 50d1a9c9f0bd3b582d6f7d89ba3e99ca |
| ZENTF_v2.20.0.1_Python_v3.11.zip | This zip file contains the zentf wheel file and the necessary scripts to set up the environment variables. Compatible with Python 3.11 | e3bb9072c804f24b1fde0cbf6727715a |
| ZENTF_v2.20.0.1_Python_v3.12.zip | This zip file contains the zentf wheel file and the necessary scripts to set up the environment variables. Compatible with Python 3.12 | 010af0caf46d5f165a2ae326b4178769 |
| ZENTF_v2.20.0.1_Python_v3.13.zip | This zip file contains the zentf wheel file and the necessary scripts to set up the environment variables. Compatible with Python 3.13 | 8c35db23ad06f1e97dd151674a778330 |
| ZENTF_v2.20.0.1_Python_v3.9.zip | This zip file contains the zentf wheel file and the necessary scripts to set up the environment variables. Compatible with Python 3.9 | 5e45a39fbe6d523bd57dc8db6b0746a1 |
| ZENTF_v2.20.0.1_C++_API.zip | This zip file contains the ZenDNN TensorFlow Plug-in with C++ APIs | f87251f783431eb0f717230c61fc9c4e |
6.0 Release Highlights
ZenDNN 6.0.0 is a major release building on the 5.2.1 runtime architecture. It deepens the Low Overhead API (LowOHA) as the primary inference path, expands MoE group GEMM and FP16 operator coverage, and adds production-grade post-op and weight caching, with corresponding extensions to BenchDNN, gtests, and operator documentation.
Overview
This is a major zentorch release that significantly expands framework support, introduces groundbreaking optimizations for Mixture of Experts (MoE) architectures, and enhances quantization capabilities for Large Language Models and Recommender Systems on AMD EPYC™ CPUs. This release transitions to PyTorch-aligned versioning, adds vLLM support up to version 0.23.0, introduces limited FP16 support for select operations, AOTI (Ahead of Time Inductor) integration, and delivers substantial performance improvements through Fused MoE operations and optimized group matmul kernels.
Improvements
1. Framework and Version Support
2. Mixture of Experts (MoE) Optimizations
3. Quantization Enhancements
4. FP16 (Float16) Support — Limited
5. Performance Optimizations
6. vLLM Plugin Enhancements
7. AOTI Integration
Breaking Changes
Known Issues
Improvements
1. Framework and Version Support
2. Features Support
3. Build Info Enhancements
4. TF-Java Support
| ZenDNN Plug-in for PyTorch (Built with PyTorch 2.11.0) |
Description | MD5SUM |
| ZENTORCH_v2.11.0.2_Python_v3.10.zip | This zip file contains the zentorch wheel file and the necessary scripts to set up the environment variables. Compatible with Python version 3.10 | 750cda740b8070bfa267da18411be038 |
| ZENTORCH_v2.11.0.2_Python_v3.11.zip | This zip file contains the zentorch wheel file and the necessary scripts to set up the environment variables. Compatible with Python version 3.11 | a0c7bbe3fa24d50f8a89ff68735c7954 |
| ZENTORCH_v2.11.0.2_Python_v3.12.zip | This zip file contains the zentorch wheel file and the necessary scripts to set up the environment variables. Compatible with Python version 3.12 | 57767d3f26599b3dd1da5c7134025070 |
| ZENTORCH_v2.11.0.2_Python_v3.13.zip | This zip file contains the zentorch wheel file and the necessary scripts to set up the environment variables. Compatible with Python version 3.13 | aa382ee0ef1709113d2324a8c7bfde82 |
| Note: Above packages can be used for LLM executions with vLLM and non LLM executions | ||
| ZenDNN Plug-in for PyTorch (Built with PyTorch 2.12.0) |
Description | |
| ZENTORCH_v2.12.0.2_Python_v3.10.zip | This zip file contains the zentorch wheel file and the necessary scripts to set up the environment variables. Compatible with Python version 3.10 | 4b6d35592bd5b5419a55928cde966869 |
| ZENTORCH_v2.12.0.2_Python_v3.11.zip | This zip file contains the zentorch wheel file and the necessary scripts to set up the environment variables. Compatible with Python version 3.11 | 9e93d8f624b3cb802c9b21d7fcfc36bb |
| ZENTORCH_v2.12.0.2_Python_v3.12.zip | This zip file contains the zentorch wheel file and the necessary scripts to set up the environment variables. Compatible with Python version 3.12 | 1927836762eeab1292eb26cd50c267fb |
| ZENTORCH_v2.12.0.2_Python_v3.13.zip | This zip file contains the zentorch wheel file and the necessary scripts to set up the environment variables. Compatible with Python version 3.13 | ac4eedaa1cf7b399b595274e23bd54bf |
| Note: Above packages can be used for non LLM executions | ||
| ZenDNN Plug-in for TensorFlow (Built with TensorFlow 2.20.0) | Description | MD5SUM |
| ZENTF_v2.20.0.0_Python_v3.10.zip | This zip file contains the zentf wheel file and the necessary scripts to set up the environment variables. Compatible with Python 3.10 | c9ebcb6f9118cc63b2ab07f432b0ce66 |
| ZENTF_v2.20.0.0_Python_v3.11.zip | This zip file contains the zentf wheel file and the necessary scripts to set up the environment variables. Compatible with Python 3.11 | 5a1df463d835d524d2a39b6944f4c051 |
| ZENTF_v2.20.0.0_Python_v3.12.zip | This zip file contains the zentf wheel file and the necessary scripts to set up the environment variables. Compatible with Python 3.12 | 8b311adc4bbf861a383f71c903e8309e |
| ZENTF_v2.20.0.0_Python_v3.13.zip | This zip file contains the zentf wheel file and the necessary scripts to set up the environment variables. Compatible with Python 3.13 | 4f24c62880c8d26f1c1750ac6f015915 |
| ZENTF_v2.20.0.0_Python_v3.9.zip | This zip file contains the zentf wheel file and the necessary scripts to set up the environment variables. Compatible with Python 3.9 | dd41a569a60574b0a13d1cba07cea2da |
| ZENTF_v2.20.0.0_C++_API.zip | This zip file contains the ZenDNN TensorFlow Plug-in with C++ APIs | 971b56eca3f3e4f0d27c0b3e375a5419 |
| ZenDNN Plug-in for TensorFlow (Built with TensorFlow 2.21.0) | Description | MD5SUM |
| ZENTF_v2.21.0.0_Python_v3.10.zip | This zip file contains the zentf wheel file and the necessary scripts to set up the environment variables. Compatible with Python 3.10 | 1871470ff213c4752ce8f7cf96ab2e5b |
| ZENTF_v2.21.0.0_Python_v3.11.zip | This zip file contains the zentf wheel file and the necessary scripts to set up the environment variables. Compatible with Python 3.11 | 6baa1424427917a73eb42d957ad456e4 |
| ZENTF_v2.21.0.0_Python_v3.12.zip | This zip file contains the zentf wheel file and the necessary scripts to set up the environment variables. Compatible with Python 3.12 | b61edbc61846ecf58227a09d071d4115 |
| ZENTF_v2.21.0.0_Python_v3.13.zip | This zip file contains the zentf wheel file and the necessary scripts to set up the environment variables. Compatible with Python 3.13 | 5028124b8b4cfa8b7d330b5f4cb9aafa |
| ZENTF_v2.21.0.0_C++_API.zip | This zip file contains the ZenDNN TensorFlow Plug-in with C++ APIs | 6cc3bb693491e7b090d243afec320a08 |
If you need technical support on ZenDNN, please file an issue ticket on the respective Github page:
Binaries are available on the PyPI repository as well and below are the links:
ZenTF: https://pypi.org/project/zentf/
ZenTorch : https://pypi.org/project/zentorch/
Refer to the user guide for more details.
Archive Access: For those requiring versions up to ZenDNN 6.0, our archives provide easy access to previous releases, ensuring you have the tools you need for any project.
Keep up-to-date on the latest product releases, news, and tips.