Build a Private Cloud with AMD Ryzen AI Max
Oct 19, 2026
Key Takeaways
- A hypervisor with GPU passthrough turns AMD hardware into a private GPU cloud -- on-premises, API-managed, and suitable for air-gapped environments.
- AMD Ryzen™ AI Max processors combine large unified-memory configurations with integrated Radeon™ graphics, enabling local execution of models that traditionally require workstation-class GPU memory. The same passthrough technique applies to discrete Radeon™ AI PRO Graphics.
- The hypervisor layer is what makes GPU hardware operationally useful at scale. VM templates, snapshots, cloning, and REST APIs enable ephemeral CI runners, isolated development environments, multi-tenant compute, and self-service AI labs -- without giving up control of your data or infrastructure.
Introduction
If you have AMD GPU hardware and want to run it as managed infrastructure rather than a collection of standalone workstations, this guide is the starting point.
AMD Ryzen™ AI Max+ 395 (Strix Halo) processors combine Zen 5 CPU cores, a large RDNA 3.5 Radeon GPU, and a high-capacity unified memory architecture in a compact package. Strix Halo systems support up to 128 GB of unified LPDDR5X memory, enabling models up to 128 billion parameters at 4-bit quantization. The newer AMD Ryzen™ AI Max+ PRO 495 (Gorgon Halo) platform raises the memory ceiling to 192 GB and can support models exceeding 300 billion parameters at 4-bit quantization. The same GPU passthrough technique covered in this guide also applies to discrete Radeon AI PRO Graphics, which provide dedicated VRAM and PCIe bandwidth for workloads that exceed what a single APU can address.
Hardware solves the compute problem; it does not solve the management problem. On bare metal, each system is essentially a standalone workstation: workloads share the same operating-system environment, CI jobs can inherit state from previous runs, and managing a fleet requires a separate provisioning and management layer.
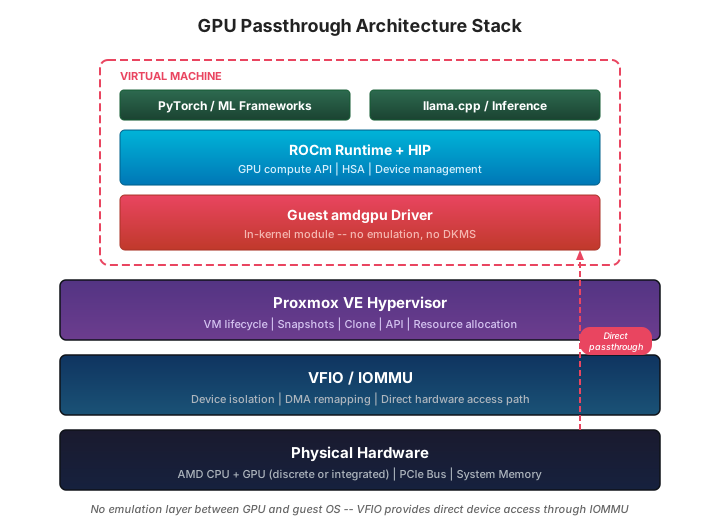
Virtualization changes that model. A hypervisor can isolate workloads in virtual machines while VFIO passes a physical GPU directly to the VM. The guest (VM) accesses the physical device directly and runs the AMD ROCm™ software stack against real AMD hardware. The hypervisor provides the infrastructure layer around that GPU:
- clone a VM from a known-good template
- snapshot it before a driver update
- provision an isolated environment for a CI job
- destroy the VM when the job completes
- manage the lifecycle through an API
This guide demonstrates that architecture using Proxmox VE, a KVM/QEMU-based virtualization platform. It walks through the complete path from host configuration to a working VM running ROCm and PyTorch on a passed-through AMD GPU. Instructions cover both integrated Radeon graphics on Ryzen AI Max processors and discrete Radeon GPUs, with callouts where the two paths diverge.
Tested Configurations
This procedure was validated end-to-end on both an integrated and discrete GPU configuration:
|
iGPU Configuration |
dGPU Configuration |
|---|---|---|
Host |
AMD Ryzen™ AI Max+ 395 |
AMD Ryzen™ Threadripper PRO 9965WX |
GPU |
Radeon™ 8060S (gfx1151, integrated) |
4x Radeon™ AI PRO R9700 (gfx1201, discrete) |
Memory |
64 GB LPDDR5X |
128 GB DDR5 |
Hypervisor |
Proxmox VE 9.1 |
Proxmox VE 9.1 |
Guest OS |
Ubuntu 24.04 HWE (7.0.0-34-generic) |
Ubuntu 24.04 HWE (7.0.0-34-generic) |
ROCm |
7.2 |
7.2 |
PyTorch |
2.9.1+rocm7.2 |
2.9.1+rocm7.2 |
PCI device IDs and bus addresses will vary by platform and SKU.
When Virtualization Makes Sense (and When It Doesn't)
Use a hypervisor when:
- CI/CD needs clean state per job. Clone a golden VM template, run the job, destroy the clone. No accumulated state, no flaky builds from leftover artifacts. This is the architecture behind ephemeral CI systems that provision GPU runners on demand.
- Multiple teams share hardware. VMs provide isolation, resource limits, and access control without giving every user root on the host.
- You need rollback. Testing a ROCm update, a kernel upgrade, or a new driver? Snapshot the VM first. If the update breaks the GPU stack, roll back in seconds instead of spending hours reimaging.
- You manage a fleet. Proxmox provides a web UI, REST API, and CLI for VM lifecycle operations across many hosts. At scale, this is significantly easier than bare-metal provisioning.
Use bare metal when:
- You are a single user on a single machine running interactive workloads
- Maximum performance matters more than reproducibility or isolation
- The system has only one GPU and you need host-side GPU access
Note that VFIO passthrough is exclusive: when a GPU is assigned to a VM, the Proxmox host cannot simultaneously use that GPU for its own workloads. The host becomes a control-plane machine and the VM owns the accelerator.
What about containers?
Docker and Podman can access AMD GPUs via --device=/dev/kfd --device=/dev/dri, and for many workloads that is the simpler path. But containers share the host's kernel and GPU driver, and for CI and multi-tenant use cases, that creates real problems:
- No GPU fault isolation. If a workload hangs the GPU or triggers a driver reset inside a container, it takes down every other container using that GPU -- and potentially the host. With a VM, a GPU hang is contained to the guest. Kill the VM, VFIO releases the device, and the host is unaffected.
- No GPU memory isolation. AMD GPUs have no hardware memory partitioning. All containers compete for the same VRAM pool. One container allocating aggressively can OOM another container's workload with no warning.
- Driver state persists between runs. The
amdgpukernel module accumulates state -- firmware contexts, page tables, command queues. A "clean" container still inherits whatever the driver has accumulated from previous workloads. For CI, this means test results can depend on what ran before. With VFIO, the guest loads its own driver from scratch every boot. - You cannot vary the kernel or driver. Every container uses the host's amdgpu module and ROCm version. If you need to test across ROCm versions, or validate a kernel upgrade, containers cannot help.
- Linux only. Containers are a Linux kernel construct. If you need GPU workloads on Windows or WSL2 -- DirectML inference, Windows driver validation, ONNX Runtime testing -- containers are not an option.
The two approaches are not mutually exclusive. A common pattern is to run containers inside a VFIO-passthrough VM: the VM provides hardware isolation and clean device state, while containers inside it handle application packaging.
What You Will Need
Hardware
Component |
Requirement |
Processor |
AMD CPU with SVM and IOMMU support |
GPU |
AMD discrete GPU (Radeon RX 7000+) or AMD Ryzen AI processor with integrated Radeon graphics |
Memory |
Sufficient to allocate to both host and guest(s) |
Software
Component |
Version |
Hypervisor |
Proxmox VE 8.x or 9.x |
Guest OS |
Ubuntu 24.04 LTS (HWE kernel required) |
ROCm |
7.2 |
PyTorch |
2.9.x with ROCm wheels from repo.radeon.com |
Installing Proxmox VE: If Proxmox is not already installed: download the ISO from proxmox.com/en/downloads, write it to a USB drive using a tool like Rufus (Windows) or dd (Linux/macOS), and boot from it. During installation, you will be asked to choose a filesystem (ext4 or ZFS) and a boot method (GRUB or systemd-boot). For most single-disk setups, ext4 with GRUB is the simplest choice. ZFS offers built-in snapshots and data integrity but uses more memory. Select UEFI boot if your system supports it. After installation, access the Proxmox web interface at https://<host-ip>:8006 and log in as root with the password you set during install.
About VFIO Passthrough
VFIO (Virtual Function I/O) binds a PCIe device exclusively to a VM. The guest OS loads native drivers and accesses the hardware directly -- the hypervisor is not in the GPU command/data path during compute operations. Modern AMD GPUs expose at least two PCIe functions: a display/VGA controller and an HDMI/DP audio controller. For the Radeon configurations covered in this guide, pass the GPU's display function and associated audio function together.
Part 1: Host Configuration
Step 1 -- Configure BIOS/UEFI
These settings are typically found under AMD CBS or Advanced CPU/PCI menus. The exact location varies by motherboard vendor.
- Enable SVM (AMD Secure Virtual Machine / AMD-V)
- Enable IOMMU (often listed under AMD CBS, NBIO, or Common Options)
- Save and reboot
Step 2 -- Enable IOMMU in the Kernel
From the Proxmox shell (accessible via the web UI's Shell tab or SSH), edit the GRUB configuration:
vi /etc/default/grub
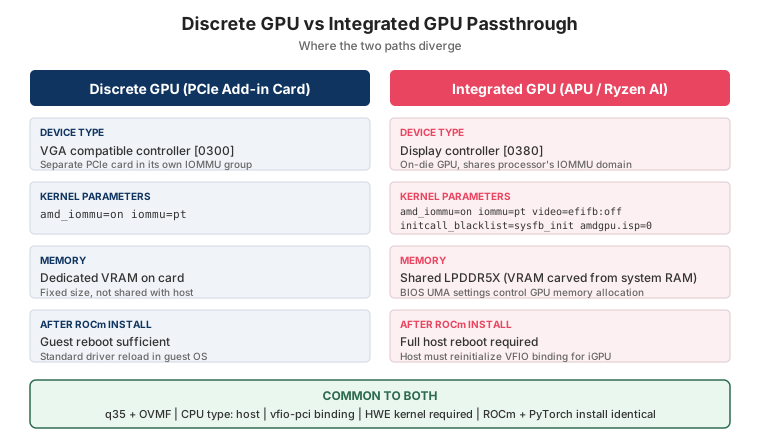
For discrete GPU passthrough:
GRUB_CMDLINE_LINUX_DEFAULT="quiet amd_iommu=on iommu=pt"
For integrated GPU (iGPU) passthrough on Ryzen AI:
GRUB_CMDLINE_LINUX_DEFAULT="quiet amd_iommu=on iommu=pt video=efifb:off initcall_blacklist=sysfb_init amdgpu.isp=0"
The parameters:
amd_iommu=onenables AMD IOMMUiommu=ptsets passthrough mode, reducing overhead for devices that are not passed throughvideo=efifb:off(iGPU only) prevents the host from claiming the iGPU's framebuffer, which would block VFIO from binding to itinitcall_blacklist=sysfb_init(iGPU only) prevents the kernel's simple framebuffer from attaching to the iGPU at early bootamdgpu.isp=0(iGPU only) disables the ISP sub-device on Strix Halo, which can interfere with clean VFIO binding
Apply and reboot:
		update-grub
reboot
Validate IOMMU is active:
dmesg | grep -e IOMMU -e AMD-Vi
You should see output confirming IOMMU is enabled and device groups have been assigned.
Step 3 -- Load VFIO Modules at Boot
Add the VFIO kernel modules so they load early in the boot process:
		cat <<'EOF' > /etc/modules-load.d/vfio.conf
vfio
vfio_pci
vfio_iommu_type1
vfio_virqfd
EOF
Alternatively, the modules can be listed one per line in /etc/modules. Both approaches are equivalent; the file-in -modules-load.d pattern is shown here for clarity.
Rebuild initramfs:
update-initramfs -u -k all
Note: This command rebuilds images for every installed kernel and can take several minutes with substantial output. This is normal.
Step 4 -- Identify the GPU
List AMD PCI devices and note the bus addresses and vendor:device ID pairs:
lspci -nn | grep -iE "amd|ati|radeon"
Discrete GPU example (Radeon™ AI PRO R9700):
		03:00.0 VGA compatible controller [0300]: Advanced Micro Devices, Inc. [AMD/ATI]
        Navi 48 [Radeon AI PRO R9700] [1002:7551]
03:00.1 Audio device [0403]: Advanced Micro Devices, Inc. [AMD/ATI]
        Navi 48 HDMI/DP Audio Controller [1002:ab40]
Integrated GPU example (Strix Halo):
		c5:00.0 Display controller [0380]: Advanced Micro Devices, Inc. [AMD/ATI]
        Strix Halo [Radeon 8060S Graphics] [1002:1586] (rev c1)
c5:00.1 Audio device [0403]: Advanced Micro Devices, Inc. [AMD/ATI]
        Radeon High Definition Audio Controller [1002:1640]
Note the difference: discrete GPUs appear as VGA compatible controller [0300], while the Strix Halo iGPU appears as Display controller [0380].
Record both vendor:device IDs (e.g., 1002:744a,1002:ab30 or 1002:1586,1002:1640). You will use these in the next step.
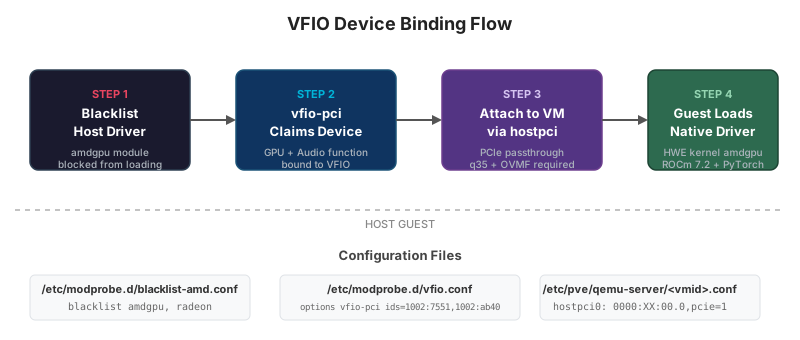
Step 5 -- Blacklist Host GPU Drivers
Prevent the host from loading GPU drivers before VFIO can bind to the device:
		cat <<'EOF' > /etc/modprobe.d/blacklist-amd.conf
blacklist amdgpu
blacklist radeon
EOF
This ensures the amdgpu kernel module does not load on the host and compete with VFIO for the device.
Step 6 -- Bind the GPU to VFIO
Create the VFIO configuration with your GPU's vendor:device IDs:
echo "options vfio-pci ids=1002:VVVV,1002:AAAA" > /etc/modprobe.d/vfio.conf
Replace VVVV and AAAA with the IDs you recorded in Step 4.
Regenerate initramfs and reboot:
		update-initramfs -u -k all
reboot
Verify VFIO Binding
After reboot, confirm that vfio-pci owns both GPU functions:
lspci -nnk -s <BUS:DEV>
For each function, you should see Kernel driver in use: vfio-pci. It is normal for Kernel modules: amdgpu to appear as available but not in use:
		c5:00.0 Display controller [0380]: ...
        Kernel driver in use: vfio-pci
        Kernel modules: amdgpu
c5:00.1 Audio device [0403]: ...
        Kernel driver in use: vfio-pci
        Kernel modules: snd_hda_intel
Part 2: VM Creation
Step 7 -- Upload an Ubuntu ISO
		wget https://releases.ubuntu.com/24.04/ubuntu-24.04.4-desktop-amd64.iso \
  -P /var/lib/vz/template/iso/
A Desktop ISO provides a GUI for initial validation. Server ISO works if you prefer headless guests.
Step 8 -- Create the VM
In the Proxmox web UI (https://<host-ip>:8006), click Create VM with these settings:
Setting |
Value |
Notes |
Machine |
q35 |
Required for PCIe passthrough |
BIOS |
OVMF (UEFI) |
Required for PCIe passthrough |
CPU type |
host |
Exposes full CPU features to guest; required for ROCm |
SCSI controller |
VirtIO SCSI single |
Best performance for virtual disks |
Disk cache |
Write back |
Commonly optimal; adjust per storage backend |
Discard/TRIM |
Enabled |
Recommended for thin-provisioned storage |
IO thread |
Enabled |
Reduces latency for disk operations |
Size CPU cores, memory, and disk according to your workload and host capacity. Do not start the VM yet.
Step 9 -- Attach the GPU
- Select the VM, navigate to Hardware
- Click Add, then PCI Device, then Raw Device
- Select the GPU's display function (the one bound to
vfio-pci) - All Functions: checked (pulls the paired audio function automatically)
- PCI-Express: checked
- Primary GPU: leave unchecked during installation (keeps noVNC console usable)
- Confirm
hostpci0withpcie=1appears in the hardware list
If the device list is empty or shows the GPU as "in use" by amdgpu, revisit Steps 5-6. Both functions must show vfio-pci as the active driver.
Step 10 -- Install the Guest OS
- Start the VM and open the Console tab
- Install Ubuntu using Erase disk and install (this applies to the VM's virtual disk only)
- After installation, reboot when prompted
Post-install validation inside the VM:
		lspci | grep -i amd     # Should show your AMD GPU
nproc                    # Should match assigned vCPU count
free -h                  # Should show allocated RAM
Part 3: ROCm and PyTorch in the Guest
With the GPU visible in the guest, install the compute stack.
Step 11 -- Install ROCm
Important: Install the HWE kernel first. The --no-dkms install method used below relies on the guest kernel's built-in amdgpu driver. Ubuntu 24.04's default kernel (6.8.0) and cloud/minimal kernel do not include the amdgpu module. The HWE (Hardware Enablement) kernel ships kernel 7.0.0+ with amdgpu built in. Without it, ROCm will install but the GPU will not be usable.
If you installed from a Desktop ISO, you likely already have the HWE kernel. For Server or cloud images, install it explicitly:
		sudo apt install -y linux-generic-hwe-24.04
sudo reboot
After rebooting, verify the HWE kernel is active:
uname -r # Should show 7.0.0-34-generic or later, not 6.8.x
Install build prerequisites:
		sudo apt update
sudo apt install -y build-essential dkms linux-headers-$(uname -r)
Note: dkms is installed here as a dependency required by the ROCm installer package, even though the next step uses --no-dkms.
Install the ROCm 7.2 stack:
		wget -q https://repo.radeon.com/amdgpu-install/7.2/ubuntu/noble/amdgpu-install_7.2.70200-1_all.deb \
  -O /tmp/amdgpu-install.deb
sudo apt install /tmp/amdgpu-install.deb
sudo amdgpu-install -y --usecase=rocm --no-dkms
The --no-dkms flag prevents the ROCm installer from building and installing an out-of-tree AMDGPU kernel module through DKMS. The passed-through GPU is still enumerated as a PCI device by the guest, and the guest's in-kernel amdgpu driver (shipped with the HWE kernel) handles the GPU. ROCm's userspace components then communicate with the GPU through the kernel driver's exposed interfaces (/dev/kfd, DRM render nodes, etc.).
Add your user to the required groups:
sudo usermod -a -G render,video $LOGNAME
Important (iGPU only): After installing ROCm on an iGPU passthrough configuration, stop the VM from the host (qm stop <vmid>), then reboot the entire Proxmox host. A guest-only reboot is not sufficient -- the host must reinitialize the VFIO device binding for ROCm to detect the GPU correctly on the next VM start.
Without a host reboot, you will see a partial failure: amdgpu loads in the guest and /dev/kfd appears, but /dev/dri does not. The kernel log will show the driver crashing during gmc_v11_0_sw_fini (memory controller teardown). The fix is a full host reboot.
For discrete GPU configurations, a guest reboot is sufficient.
Verify ROCm
After restarting (host reboot for iGPU, guest reboot for dGPU) and starting the VM:
rocminfo
iGPU example output (abbreviated):
		*******
Agent 2
*******
  Name:                    gfx1151
  Marketing Name:          Radeon 8050S Graphics
  Vendor Name:             AMD
dGPU example output (abbreviated):
		*******
Agent 2
*******
  Name:                    gfx1201
  Uuid:                    GPU-XX
  Marketing Name:          AMD Radeon AI PRO R9700
  Vendor Name:             AMD
The GPU appearing as a named agent with a gfx target confirms ROCm can communicate with the passed-through GPU.
Note: rocminfo may report a slightly different marketing name than the system's advertised SKU depending on the firmware revision and ROCm version. The gfx target ID is the authoritative identifier.
Step 12 -- Install PyTorch
AMD provides tested ROCm wheels on repo.radeon.com. These are recommended over the wheels on pytorch.org, which change frequently with nightly builds and are not extensively validated by AMD.
Create a Python environment and install the validated wheels:
		sudo apt install -y python3-pip python3-venv
python3 -m venv rocm-env
source rocm-env/bin/activate
pip3 install --upgrade pip wheel

wget https://repo.radeon.com/rocm/manylinux/rocm-rel-7.2/torch-2.9.1%2Brocm7.2.0.lw.git7e1940d4-cp312-cp312-linux_x86_64.whl
wget https://repo.radeon.com/rocm/manylinux/rocm-rel-7.2/torchvision-0.24.0%2Brocm7.2.0.gitb919bd0c-cp312-cp312-linux_x86_64.whl
wget https://repo.radeon.com/rocm/manylinux/rocm-rel-7.2/triton-3.5.1%2Brocm7.2.0.gita272dfa8-cp312-cp312-linux_x86_64.whl
wget https://repo.radeon.com/rocm/manylinux/rocm-rel-7.2/torchaudio-2.9.0%2Brocm7.2.0.gite3c6ee2b-cp312-cp312-linux_x86_64.whl

pip3 install \
  torch-2.9.1+rocm7.2.0.lw.git7e1940d4-cp312-cp312-linux_x86_64.whl \
  torchvision-0.24.0+rocm7.2.0.gitb919bd0c-cp312-cp312-linux_x86_64.whl \
  torchaudio-2.9.0+rocm7.2.0.gite3c6ee2b-cp312-cp312-linux_x86_64.whl \
  triton-3.5.1+rocm7.2.0.gita272dfa8-cp312-cp312-linux_x86_64.whl
Check the ROCm compatibility matrix for the latest wheel versions matching your Python and ROCm release.
Verify PyTorch
		python3 -c 'import torch; print("Available:", torch.cuda.is_available())'
python3 -c "import torch; print('Device:', torch.cuda.get_device_name(0))"
python3 -m torch.utils.collect_env
Expected: Available: True and a device name matching your GPU.
In PyTorch, torch.cuda is the generic GPU access API. On AMD hardware with ROCm, it routes through HIP. No CUDA hardware is required.
Performance Notes
VFIO gives the guest direct access to the physical GPU rather than emulating a virtual GPU device. For sustained compute workloads, GPU execution occurs directly on the passed-through hardware. The primary overhead is in device initialization, interrupt routing, and IOMMU address translation, which are negligible during inference or training workloads.
On Strix Halo, the system memory is physically shared by the CPU and GPU rather than being dedicated VRAM. The amount addressable by the passed-through GPU depends on the platform's BIOS UMA carve-out and GTT configuration. For LLM workloads where memory capacity and bandwidth are critical, tuning the BIOS UMA carve-out and kernel GTT parameters (amdgpu.gttsize, ttm.pages_limit) can significantly increase the memory available to the GPU.
Part 4: From VM to Infrastructure
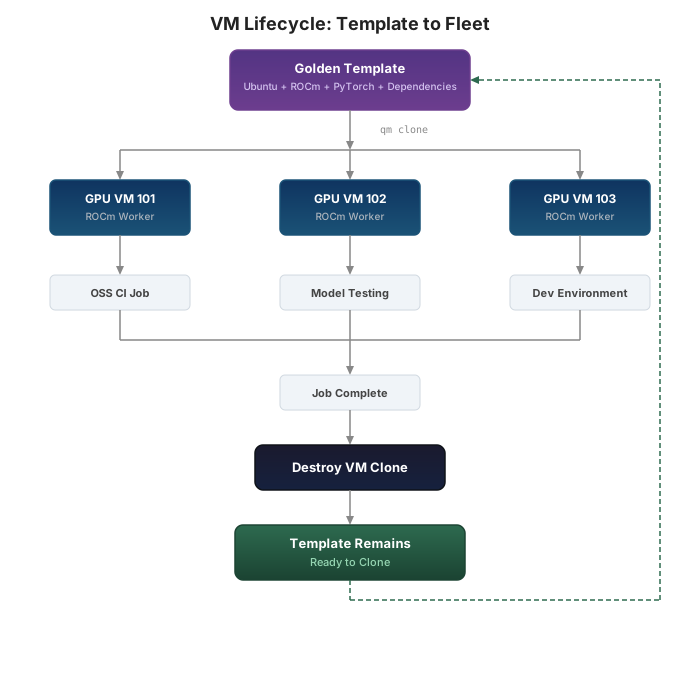
A single VM with a passed-through GPU is useful. The real value comes from turning one working VM into a fleet.
Template Cloning
Once you have a fully configured VM (OS, ROCm, PyTorch, dependencies), convert it to a template:
		# On the Proxmox host:
qm template <vmid>
Clone it to create identical environments:
		# Full clone (independent copy):
qm clone <template-id> <new-id> --full --name gpu-worker-01

# Start the clone:
qm start <new-id>
Each clone starts from known-good state. For CI, this means every job gets the exact same environment. For development, each engineer gets an isolated GPU-equipped VM.
On systems with multiple GPUs (or multiple hosts with one GPU each), assign a different GPU to each clone by editing its configuration:
qm set <new-id> --hostpci0 0000:<BUS:DEV.FUNC>,pcie=1
API-Driven Lifecycle
Proxmox's REST API supports the full VM lifecycle. An orchestrator can provision GPU-equipped VMs on demand, run a job, and tear them down:
		POST /api2/json/nodes/{node}/qemu/{template-id}/clone
POST /api2/json/nodes/{node}/qemu/{new-id}/status/start
  ... job runs ...
POST /api2/json/nodes/{node}/qemu/{new-id}/status/stop
DELETE /api2/json/nodes/{node}/qemu/{new-id}
This is the foundation for ephemeral CI runners on AMD hardware. The qm CLI provides the same operations for scripting:
		# Provision, run, destroy:
qm clone 9000 501 --full --name ci-runner-$$
qm start 501
# ... wait for job ...
qm stop 501
qm destroy 501 --purge
Fleet Management
Across a rack of Strix Halo systems or a mixed fleet of APU and discrete GPU hosts, Proxmox provides centralized management through its cluster features. Each host contributes its GPU(s) to the pool. An orchestrator routes jobs to available hardware based on GPU type, label, or capacity.
For a practical example: the DevLab Dispatch system runs ephemeral CI for open-source projects on AMD hardware using exactly this architecture -- Proxmox VMs with passed-through GPUs, provisioned per job, destroyed after completion.
Troubleshooting
| Symptom | Likely Cause | Resolution |
|---|---|---|
| Black screen in noVNC after login | GNOME session startup delay | Wait 1-2 minutes; initial session over virtual display is slow |
GPU not listed in guest lspci |
Device not attached or VM not restarted | Verify hostpci0 in VM Hardware; fully stop and restart the VM |
Host loads amdgpu despite blacklist |
Blacklist not applied or initramfs stale | Verify /etc/modprobe.d/blacklist-amd.conf exists, run update-initramfs -u -k all, reboot |
| IOMMU groups too large | BIOS ACS not enabled | Check motherboard documentation for ACS support |
rocminfo shows CPU agents but no GPU agent |
Host not rebooted after ROCm install (iGPU) | Stop VM, reboot the Proxmox host, then start VM |
vfio-pci fails to bind iGPU |
amdgpu or framebuffer still claiming device |
Verify video=efifb:off, initcall_blacklist=sysfb_init, and amdgpu.isp=0 are all in GRUB cmdline |
GPU appears in lspci but /dev/kfd is missing |
ROCm userspace not installed or group membership | Verify ROCm install completed; check groups output includes render and video |
| /dev/kfd exists but /dev/dri is missing | iGPU: host not rebooted after ROCm install | The amdgpu driver loaded but crashed during memory controller init (gmc_v11_0_sw_fini). Stop VM, reboot host, start VM |
| iGPU disappears after VM stop/start cycle | Host VFIO binding lost | Full host reboot required to reinitialize VFIO for the iGPU |
| Host loses display after framebuffer changes | video=efifb:off removed host console output |
Expected on headless/iGPU systems; manage the host via SSH or the Proxmox web UI |
| GPU memory capacity unexpectedly low | BIOS UMA carve-out too small | Adjust UMA/VRAM allocation in BIOS settings; see VRAM vs GTT tuning guide |
| "ROCk module is NOT loaded" | Guest kernel does not include amdgpu |
Install the HWE kernel (linux-generic-hwe-24.04) and reboot the VM; the default 6.8.0 and cloud/minimal kernels do not ship amdgpu |
Quick Reference
| Task | Command |
|---|---|
| List AMD PCI devices | lspci -nn | grep -iE "amd|ati|radeon" |
| Check device driver binding | lspci -nnk -s <BUS:DEV.FUNC> |
| List VMs | qm list |
| Start / stop / destroy a VM | qm start <id>, qm stop <id>, qm destroy <id> |
| Clone from template | qm clone <template-id> <new-id> --full |
| Snapshot a VM | qm snapshot <id> <name> |
| Convert VM to template | qm template <id> |
| Access Proxmox web UI | https://<host-ip>:8006 |
Footnotes
Test configuration: AMD Ryzen™ AI MAX+ 395 / Radeon 8060S (gfx1151), 128 GB LPDDR5X, Proxmox VE 9.x, Ubuntu 24.04 HWE guest, ROCm 7.2, PyTorch 2.9.1. iGPU passthrough via VFIO with IOMMU enabled. The same host configuration steps apply to discrete Radeon GPUs; PCI device IDs and bus addresses will vary by platform.

Related Blogs
-
FP16 GEMM Optimization on AMD RDNA™ 3 and RDNA™ 4 Architectures — ROCm Blogs
Learn how to build an FP16 GEMM kernel with WMMA on AMD RDNA 3 and RDNA 4, one optimization at a time, and approach hipBLASLt performance.
October 15, 2026
-
Day 0 Support for Muse Spark Open on AMD
AMD is excited to announce Day-0 support for Meta’s latest Muse Spark Open model family on AMD Instinct™ MI350X and MI355X GPUs
October 15, 2026
-
Introducing FastFlow SDK
Explore AMD FastFlow-SDK for local AI development on AMD Ryzen™ AI NPUs, from running models to customizing inference and optimizing operators with FastFlow, IRON, and HRX.
October 15, 2026
-
MiniCPM Day 0 Support Across AMD Hardware
Explore Day 0 support for MiniCPM-V 4.7 on AMD Radeon™ GPUs, Ryzen™ AI Max processors, and Ryzen™ AI NPUs for on-device AI inference.
October 14, 2026
-
Kimi K3 on AMD Instinct GPUs with TokenSpeed
TokenSpeed delivers fast, agentic LLM inference on AMD Instinct™ MI355X GPUs, with optimized kernels and leading Kimi K3 performance.
October 09, 2026
-
scikit workloads with AOCL Data Analytics
Accelerate supported scikit-learn workloads with AOCL-Data Analytics while keeping your existing Python code and familiar scikit-learn APIs.
October 09, 2026
-
MoRI UMBP Empowers AMD Instinct GPUs
See how UMBP, MoRI and SGLang optimize KV cache reuse to boost AMD Instinct™ MI355X GPU agentic AI performance and cost efficiency
October 09, 2026
-
Completing the GPU Performance Picture: Understanding TAF Alongside Peak FLOPs and MAF — ROCm Blogs
Learn how Typical Attained FLOPs complements Peak FLOPs and Max-Achievable FLOPs, including the methodology and MI325X results
October 05, 2026