Exascale Was the Beginning: AMD Instinct™ MI430X GPUs
Nov 12, 2026
AMD powers much of the world's leading scientific computing, from exascale supercomputers driving discovery in the United States and Europe to Lux, the first US Genesis Mission system for AI-driven science. With leadership CPUs, GPUs, FPGAs, networking and AMD ROCm™ open software stack, AMD gives nations, laboratories and enterprises a single open platform for high-performance computing, AI for science, sovereign AI, agentic AI and the path to quantum computing.
That breadth isn't an accident. It reflects a conviction that shapes every system we build: Science doesn't run on one kind of compute.
The world's most important challenges no longer fit a single computing model. Climate science, drug discovery, advanced manufacturing, national security, sovereign AI, and quantum research increasingly using diversified computing models working together as one system. The question facing our industry is no longer "which processor wins?" It is "how do we bring the right compute to the right workload at the right time?"
AMD has been answering that question in production for years. Frontier broke the exascale barrier. El Capitan brought AI-assisted simulation to the national security mission. LUMI put climate and cancer research on open infrastructure. And Lux, the first operational DOE Genesis Mission AI for Science supercomputer, is live at Oak Ridge National Laboratory today.
Exascale was the beginning. The AMD Instinct™ MI430X GPU is what comes next.
AMD Instinct MI430X GPU
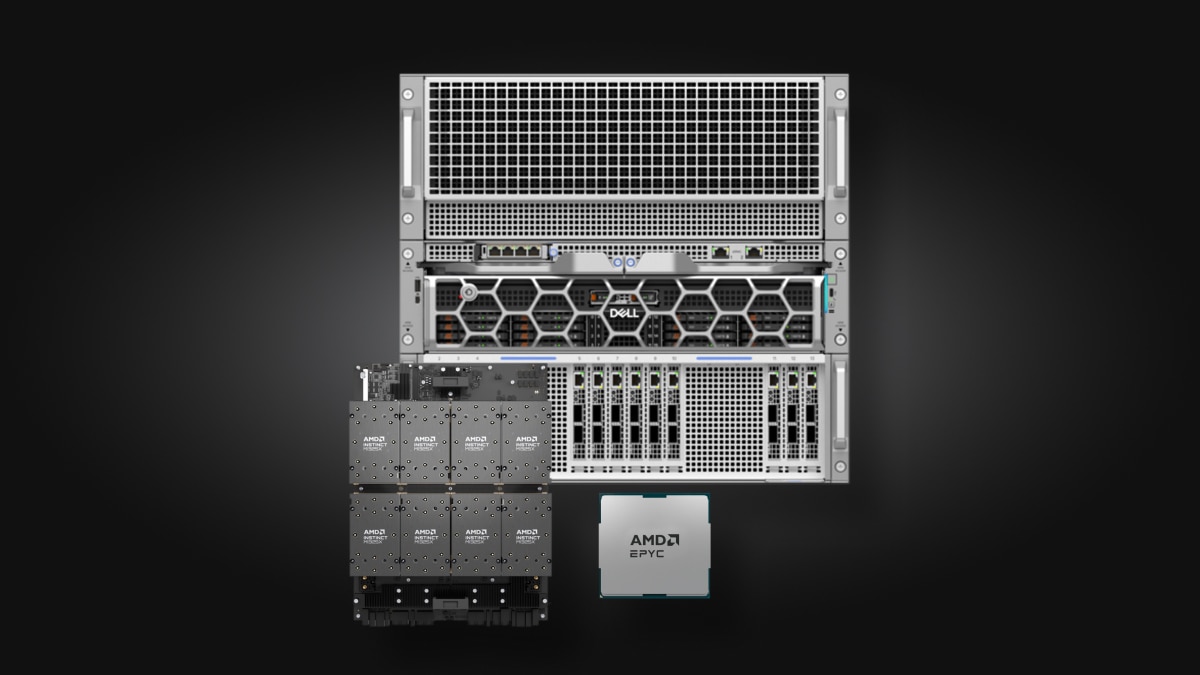
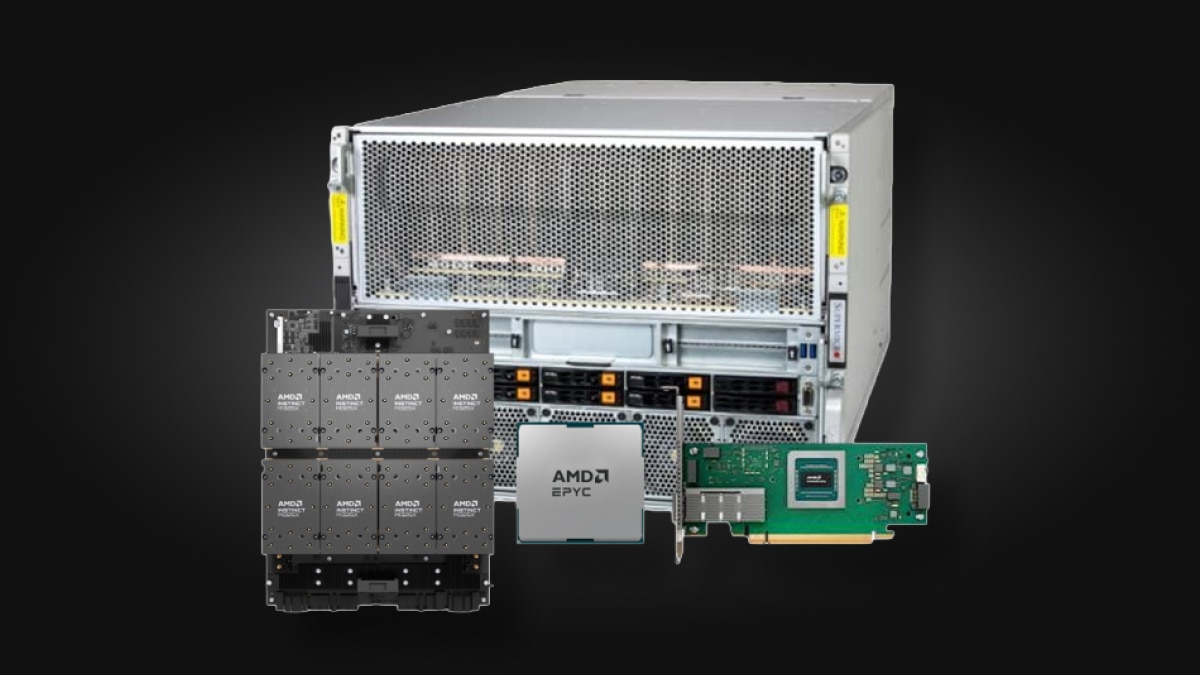
The AMD Instinct MI430X is the first GPU designed from the outset for the convergence of high-precision compute and AI for science. Built on the AMD CDNA™ 5 architecture, it pairs up to 288 TFLOPS of peak native FP64 with 432 GB of HBM4 at 23.3 TB/s memory bandwidth and 9.2 PF of peak FP4 performance providing the right mix of high precision and AI compute.
MI430X carries 432 GB of HBM4 at up to 23.3 TB/s, 50% more memory capacity than Nvidia Vera Rubin. Larger meshes, more atoms and longer sequences stay resident on the GPU instead of being split across nodes and the network. Memory also matters for precision: an emulated FP64 matrix multiply needs up to roughly three times the memory of a native one, so dense native FP64 compute supports memory efficiency.
When HPC workloads need more than a single GPU, The AMD Instinct MI430X GPU pairs a 6th Gen AMD EPYC™ Server CPU SP7 host with four GPUs in a fully connected, glue-less mesh using AMD Infinity Fabric™ technology where every GPU holds a direct link to each of the other three, delivering up to 384 GB/s unidirectional per GPU and up to 12.3 Tbps of scale-up bandwidth across the node. For scientific codes where domain-decomposed simulation is dominated by halo exchange, reductions, and small-message collectives. This traffic is far more sensitive to the latency of each hop than to the size of the scale-up domain so a switchless all-to-all removes a hop, a power budget, and a failure domain from every one of those exchanges.
All combined, these design choices result in significant generational performance gains on AMD Instinct MI430X GPUs relative to AMD Instinct MI300A:
Benchmark |
MI430X (Projected) |
MI430X (Projected Result) |
HPL |
3.96x |
190 TFLOPs |
HPL-MxP (FP16) |
4.16x |
1790 TFLOPs |
BabelStream |
5.27x |
20 TB/s |
HPCG |
5.57x |
3.08 TFLOPs |
Table 1: AMD Instinct MI430X GPU Performance Comparisons relative to AMD Instinct MI300A
AMD Instinct MI430X nodes maintain the shared memory programming model that MI300A customers have built around, using glue-less Infinity Fabric™ to coherently connect four GPUs to an EPYC™ "Venice" SP7 host. Code and expertise carry forward.
Native FP64 Versus Emulated FP64
Some in the industry feel that native double precision can be safely deprioritized in HPC accelerators. It rests on two assertions: that HPC workloads are memory-bandwidth-bound, and that low-precision tensor cores can emulate FP64 on demand with accuracy when required.
In the paper FP64 Performance and the Limits of Ozaki Emulation on HPC Systems, presented at SC26, AMD researchers tested both claims directly, profiling 47 workload configurations across 11 applications and benchmarks on AMD Instinct MI350X and MI355X GPUs, then evaluating Ozaki GEMM emulation across three current GPU architectures. Three findings stand out.
- Emulation is a dense GEMM technique, and HPC is mostly not dense GEMM. They are vector operations, reductions, stencils, sparse linear algebra, and application-specific kernels; none of which reshape into a large dense matrix multiply. Based on a sample of HPC applications as noted in the above mentioned white paper, less than 10% of HPC ecosystem is dense enough and GEMM-shaped enough for emulated FP64 to add value.
- Characterizing HPC workloads as “memory bound” does not deprioritize native FP64. It can make HPC workloads compute bound instead. On the AMD Instinct™ MI355X GPU, most profiled workloads do sit on the bandwidth side of that line. But the study's roofline projections show that as native FP64 throughput is cut while memory bandwidth increases, kernels that are comfortably memory-bound today become compute-bound on FP64-reduced architectures.
- Even inside the aforementioned favorable 10% of HPC workloads, emulation only benefits a large matrix size and is substantially slower below it. It pushes total memory footprint to roughly up to three times that of a native FP64 GEMM and is sensitive to how operands happen to be scaled, where native FP64 is invariant. Awkward matrix shapes cost considerably more than they cost native hardware. Ozaki emulation is a well-engineered technique that does what it was designed to do. It just happens to serve a very narrow slice of HPC work.
What This Means for Your Workload and Budget
The practical question isn't whether emulation is impressive. It's whether it fits what your code actually does.
Workload Class |
Profiled Code |
Does Emulation Help? |
Dense linear algebra |
rocHPL |
Sometime – the one application in the set with a dominant DGEMM kernel. Note that HPL currently prohibits emulation. |
Sparse iterative linear algebra |
rocHPCG |
No – not GEMM-shaped |
Stencils and hydrodynamics |
TeaLeaf, CloverLeaf, Laghos, PENNANT |
No – mesh and element kernels |
High-order finite element |
CEED Bake-Off |
No – operator evaluation, not dense GEMM |
Monte Carlo and particle transport |
XSBench, Kripke |
No – irregular and gather-heavy |
Classical molecular dynamics |
LAMMPS |
No – neighbor lists and short-range forces |
Device memory bandwidth |
BabelStream |
No - bounded by HBM |
Eleven profiled applications, one qualified yes. For the rest, the FP64 question is settled before emulation enters the conversation: these codes need native double-precision vector throughput and memory bandwidth.
Native FP64 changes the economics as well as the science. When one accelerator runs simulation at full double precision and AI at FP4, you run one system, one software stack and one operations team instead of separate HPC and AI clusters. More memory per GPU means fewer GPUs for the same problem, and fewer nodes means less networking, power and floor space.
This is why the AMD Instinct MI430X GPU has been selected for flagship scientific systems on two continents: Discovery at Oak Ridge National Laboratory, the successor to Frontier; Alice Recoque, France's first exascale system, funded by EuroHPC; and Herder at HLRS in Germany. National laboratories and sovereign programs plan years ahead, and they require native FP64, along with lower precision support for AI in science.
No-Compromise Scientific Computing
Memory bandwidth, native FP64 throughput, and GEMM emulation address complementary rather than interchangeable parts of the HPC portfolio. A system that optimizes one at the expense of the others hasn't become more efficient — it has become more specialized, and it has pushed the cost of that specialization onto the science teams who have to work around it.
A supercomputer is more than the sum of its GPUs, and hardware architecture is only one part of the answer. ROCm™ platform gives developers open software to port, inspect, and optimize both HPC and AI applications, with a long-term support model planned to give production deployments two years of stability. AMD HPC Assistant brings an AI coding assistant built specifically for high-performance computing. And our networking strategy is built on open industry standards, so your infrastructure won’t become captive to one proprietary fabric.
The combined solution offered by AMD with tailored hardware, software, solutions and ecosystem are what supercomputers need. Frontier, El Capitan, LUMI, and Lux are running today. Alice Recoque will anchor European sovereign AI infrastructure. LUMI-AI and LUMI-IQ at CSC Finland and Herder at HLRS will deploy MI430X with 6th Gen EPYC.
Get Started
Bring us your two most important codes. AMD's HPC and AI team will look at where they land on the the AMD Instinct MI430X GPU roofline and map your path forward, whether that is porting with HIP, scaling on ROCm, or planning a procurement around native FP64.
You should not have to choose between strong AI performance and uncompromised HPC capability.
With the AMD Instinct MI430X GPUs, you won't.
Your next scientific breakthrough starts here. Let's build it together.
Email HPCAI@AMD.com to start the conversation, and visit AMD at SC26 booth #3028 in Chicago, November 15–20 — and join the full presentation of FP64 Performance and the Limits of Ozaki Emulation on HPC Systems for the complete methodology, dataset, and results.
Endnotes and Disclosures
MI430X performance figures are projections based on analytical models and preliminary silicon targets; they are not measured results and are subject to change. MI300A comparison data measured; MI430X projected. Gen-on-gen and competitive comparison data last updated Nov 2026. NVIDIA B200, Rubin, and GB300 figures based on AMD testing." B200 and GB300 results are AMD testing (configurations in the paper). Vera Rubin figures are based on NVIDIA published specifications (preliminary). Also add: "Unless stated otherwise, AMD has not tested or verified the third-party claims found herein. GD-182a. FP64 emulation analysis, roofline data, and all Ozaki findings cited in this post are drawn from FP64 Performance and the Limits of Ozaki Emulation on HPC Systems, research conducted and authored by AMD and presented at SC26; see the paper for complete methodology, test configurations, accuracy and reproducibility analysis, and full results. Roofline dataset comprises 47 application configurations and 131 plotted kernel instances on AMD Instinct MI350X/MI355X. Timelines, roadmaps, and product release dates shown herein are plans only and subject to change.
This blog may contain forward-looking statements concerning Advanced Micro Devices, Inc. (AMD), which are made pursuant to the Safe Harbor provisions of the Private Securities Litigation Reform Act of 1995. Forward-looking statements are commonly identified by words such as "would," "may," "expects," "believes," "plans," "intends," "projects" and other terms with similar meaning. Investors are cautioned that any forward-looking statements in this blog are based on current beliefs, assumptions and expectations, speak only as of the date of this blog and involve risks and uncertainties that could cause actual results to differ materially from current expectations. Investors are urged to review in detail the risks and uncertainties in AMD's Securities and Exchange Commission filings, including but not limited to AMD's most recent reports on Forms 10-K and 10-Q. AMD does not assume, and hereby disclaims, any obligation to update forward-looking statements made in this blog, except as may be required by law.
AMD, the AMD Arrow logo, AMD CDNA, AMD Instinct, AMD Pensando, EPYC, Infinity Fabric, ROCm, and combinations thereof are trademarks of Advanced Micro Devices, Inc. Other product names are for informational purposes only and may be trademarks of their respective owners.

Related Blogs
-
AI Is the New Electricity. And the Meter Is Running.
AMD helps enterprises scale AI while managing costs with leadership compute, open platforms and ecosystem partnerships.
November 11, 2026
-
Parallelism for Long-Context Serving: GLM-5.3-Flash on MI300X — ROCm Blogs
Measured throughput of GLM-5.3-Flash on MI300X: how KV-cache capacity shapes TP8 and DP8+EP8 serving, with BF16 and FP8 KV cache.
November 10, 2026
-
Accelerating GLM-5.2 on AMD Instinct MI355X: EvalScope Benchmarks with Prefix Caching — ROCm Blogs
Learn how to optimize GLM-5.2 FP8 long-context inference on AMD Instinct MI355X GPUs using prefix caching and end-to-end inference stack tuning.
November 10, 2026
-
Introducing AMD Instinct™ Coder 355: A Turnkey AI Assisted Coding Platform for the Enterprise
The AMD Instinct Coder 355 is a turnkey, fully supported, on-premises AI coding platform that combines AMD EPYC™ processors, AMD Instinct™ GPUs, Dell PowerEdge servers, Spectro Cloud PaletteAI Inference Launchpad software, and the GLM-5.3 model into a single integrated solution.
November 09, 2026
-
Introducing AMD Instinct™ Coder 355: The next generation AI Assisted Coding Platform for the Enterprise
The AMD Instinct Coder 355 is a turnkey, fully supported, on-premises AI coding platform that combines AMD EPYC™ processors, AMD Instinct™ GPUs, Supermicro® AI servers, Spectro Cloud PaletteAI Inference Launchpad software, and the GLM-5.3 model into a single integrated solution.
November 09, 2026
-
Project Zenith Comes to AMD Ryzen™ AI Halo: Ready to Code. Ready to Build.
Project Zenith brings Microsoft's ready-to-code Windows 11 experience to the AMD Ryzen™ AI Halo Developer Platform, creating a powerful new starting point for local AI development.
November 09, 2026
-
ROCm InferaSim: Cut LLM Serving Trial Costs and Deploy the Best Configuration — ROCm Blogs
Learn how ROCm InferaSim predicts LLM serving performance on AMD Instinct GPUs from a few short runs, so you can deploy the best configuration.
November 05, 2026
-
PrimusClaw: An Open-Source Managed Agent Runtime for AMD Instinct GPU Clusters — ROCm Blogs
PrimusClaw is an open-source managed agent runtime that hosts durable, sandboxed agent sessions on your own AMD Instinct GPU clusters.
November 05, 2026