


Overview
Optimized for AI Workloads
Some teams need to train or fine-tune a model; others need to put an existing open model into production. ROCm supports both paths on AMD GPUs, with workflows for distributed training and software to optimize, serve, and operate AI inference at scale.
AI Inference
Production AI Inference with ROCm
Deploy leading open models on AMD GPUs using a fully open-source inference stack. Get up and running with prebuilt containers and upstream framework support.
Choose Your Engine
Start Serving Open Models
AMD ROCm delivers an end-to-end inference stack with upstream framework support, vLLM or SGLang containers and more, so your team can start with established inference software before integrating a model into your application.
Smaller Footprint
Improve Memory and Serving Efficiency
ROCm pairs quantized model packages with native low-precision execution and optimized transformer hot-path kernels, to reduce tuning effort while maximizing throughput and efficiency for real-world serving.
Meet Growing Demand
Scale Inference Across GPUs and Nodes
When a model or request volume outgrows one server, distribute serving across AMD Instinct™ GPUs. Supported deployments can separate prefill and decode so teams can allocate resources to each stage.
Fleet Control
Operate Inference on Kubernetes
ROCm integrates with Kubernetes through the AMD GPU Operator, built-in telemetry, and a modular driver architecture - supporting automated rollout, observability, and predictable lifecycle management across secure and air-gapped environments.
AI Training
End-to-End AI Training at Scale on AMD GPUs
From unified workflows to cluster-scale reliability—Primus simplifies and accelerates large-model training.
Framework Flexibility
Launch Training Runs You Can Repeat
Start training on AMD Instinct™ GPUs with unified workflows through AMD Primus recipes for Megatron-LM, PyTorch TorchTitan, or JAX MaxText. Use a single CLI and reusable configurations to rerun experiments and compare changes.
Keep GPU’s Busy
Address Transformer Training Bottlenecks
Primus improves training throughput and GPU utilization with optimized kernels and communication-aware acceleration. Teams can use these capabilities through the full Primus stack or plug Primus Turbo into custom training environments.
Keep Job’s Moving
Scalable Distributed Training
When a model outgrows one server, Primus helps distribute training across AMD Instinct™ GPUs and nodes. Primus-SaFE uses topology-aware placement and automatic retries to help long-running jobs recover from interruptions as clusters grow.
Check, Then Track
Enterprise-Ready Training Operations
Primus helps teams assess node health before launching large training jobs. During training, its telemetry and dashboards provide visibility into performance and cluster health, helping teams identify issues and troubleshoot them faster.
Latest News
Read about the latest advancements in AI development using ROCm.
-
Day 0 Support for Muse Spark Open on AMD
AMD is excited to announce Day-0 support for Meta’s latest Muse Spark Open model family on AMD Instinct™ MI350X and MI355X GPUs
October 15, 2026
-
Long Context, One Node: Serving GLM-5.3-FP8 on MI300X with DP8+EP8 — ROCm Blogs
Learn how to serve GLM-5.3-FP8 on one AMD Instinct™ MI300X node with DP8+EP8 and vLLM v0.28 for long-context workloads, and compare it with TP=8.
October 13, 2026
-
Meet the Next AMD Ryzen™ AI Halo
Meet the next AMD Ryzen™ AI Halo developer platform, powered by the AMD Ryzen™ AI Max+ PRO 495 processor. Run larger local LLMs, up to 300B parameters…
October 12, 2026
-
Kimi K3 on AMD Instinct GPUs with TokenSpeed
TokenSpeed delivers fast, agentic LLM inference on AMD Instinct™ MI355X GPUs, with optimized kernels and leading Kimi K3 performance.
October 09, 2026
-
MangoBoost Delivers Open AI Models Powered by AMD
Mango Inference a serverless inference service providing production-ready access to open models powered by AMD Instinct™ GPUs and AMD ROCm™ software
October 09, 2026
-
MoRI UMBP Empowers AMD Instinct GPUs
See how UMBP, MoRI and SGLang optimize KV cache reuse to boost AMD Instinct™ MI355X GPU agentic AI performance and cost efficiency
October 09, 2026
-
Pre-Training Hybrid LLMs from Scratch in Primus on AMD Instinct™ GPUs — ROCm Blogs
Pre-train hybrid LLMs mixing MLA attention with Gated DeltaNet, Kimi Delta Attention and Mamba2 mixers on AMD Instinct MI355X GPUs, with open recipes.
October 07, 2026
-
DI Series: Serving Kimi-K3 MXFP4 Wide-EP Disaggregated on AMD Instinct MI300X and MI325X — ROCm Blogs
Learn how to serve a 1.4 TiB Kimi-K3 MXFP4 mixture-of-experts model disaggregated across AMD Instinct MI300X and MI325X GPUs.
October 07, 2026

Supported Hardware

Developer Resources
Receive the latest ROCm news.
Footnotes
©2024 Advanced Micro Devices, Inc. All rights reserved. AMD, the AMD Arrow logo, AMD ROCm, AMD Instinct, EPYC, Radeon Instinct, and combinations thereof are trademarks of Advanced Micro Devices, Inc. PyTorch is a trademark or registered trademark of PyTorch. Other product names used in this publication are for identification purposes only and may be trademarks of their respective companies.
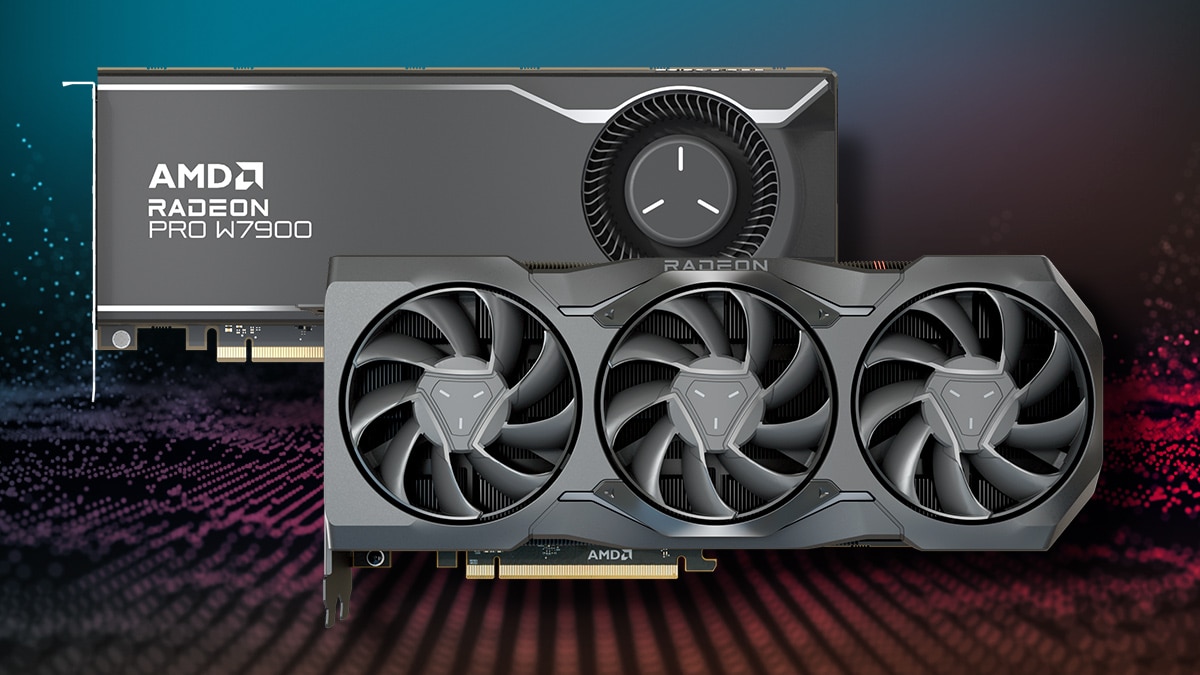
- For a full list of Radeon parts supported by ROCm, go to https://rocm.docs.amd.com/en/latest/reference/gpu-arch-specs.html